Generate a Let’s Encrypt certificate using DNS challenge

UPDATE:  The letsencrypt.sh script has been renamed to dehydrated.  Make sure you are using the updated dehydrated script if you are following this guide.

The Let’s Encrypt project has recently unveiled support for the DNS-01 challenge type for issuing certificates and the official Let’s Encrypt project added support with the recent addition of this PR on Github, which enables challenge support  on the server side of things but does not enable the challenge in the client (yet).  This is great news for those that are looking for more flexibility and additional options when creating and manage LE certificates.  For example, if you are not running a web server and rely strictly on having a DNS record to verify domain ownership, this new DNS challenge option is a great alternative.

I am still learning the ins and outs of LE but so far it has been an overwhelmingly positive experience.  I feel like tools like LE will be the future of SSL and certificate creation and management, especially as the ecosystem evolves more in the direction of automation and various industries continue to push for higher levels of security.

One of the big issues with implementing DNS support into a LE client as it currently stands is the large range of public DNS providers that have no standardized API support.  It becomes very difficult to automate the process of issuing and renewing certificates with the lack of standardization and API’s using LE.  The letsencrypt.sh project mentioned below is nice because it has implemented support for a few of the common DNS providers (AWS, CloudFlare, etc.) as hooks which allow the letsencrytpt.sh client to connect to their API’s and create the necessary DNS records.  Additionally, if support for a DNS provider doesn’t exist it is easy to add it by creating your own custom hooks.

letsencrypt.sh is a nice choice because it is flexible and just works.  It is essentially an implementation of the LE client, written in bash.  This is an attractive option because it is well documented, easy to download and use and is also very straight forward.  To use the DNS feature you will need to create a hook, which is responsible for placing the correct challenge in your DNS record.

Here is an example hook that is used for connecting with AWS Route53 for issuing certificates for subdomains.  After downloading the example hook script, you need to run a few commands to get things working.  You can grab it with the following command.

curl -o route53.rb https://gist.githubusercontent.com/tache/3b6760784c098c9139c6/raw/33fe6e0791a7d40ce7cdf14019b7d31801d4ab05/hook.rb
chmod +x route53.rb

You also need to make sure you have the Ruby dependencies installed on your system for the script to work.  The process of installing gems is pretty simple but there was an issue with the version of awesome_print at the time I made this so I had to install a specific version to get things working.  Otherwise, the installation of the other gems was straight forward.  NOTE: These gems are specific to the rout53.rb script.  If you use another hook that doesn’t require these dependencies you can skip the gems installations.

sudo gem install awesome_print -v 1.6.0
sudo gem install aws-sdk
sudo gem install pry
sudo gem install domainatrix

After you install the dependencies, you can run the letsencrypt script .

./letsencrypt.sh

You can see a few different options in this command.

The following command specifies the domain in the command (rather than adding a domains.txt file to reference), the custom hook that we have downloaded, and specifies the type of challenge to use, which is the dns-01 challenge.

./letsencrypt.sh --cron --domain test.example.com --hook ./route53.rb --challenge dns-01

Make sure you have your AWS credentials configured, otherwise the certificate creation will fail.  Here’s what the output of a successful certificate creation might look like.

#
# !! WARNING !! No main config file found, using default config!
#
Processing test.example.com
 + Signing domains...
 + Generating private key...
 + Generating signing request...
 + Requesting challenge for test.example.com...
-------------------->
 Domain: test.example.com
 Root: example.com
 Stage: deploy_challenge
Challenge: yabPBE9YvPXGFjslRtqXh-qK27QlWQgFlTusqcDzUMQ
{
 :change_info => {
 :id => "/change/C3K8MHKLB6IRKZ",
 :status => "PENDING",
 :submitted_at => 2016-08-08 17:54:50 UTC
 }
}
--------------------<
 + Responding to challenge for test.example.com...
-------------------->
 Domain: test.example.com
 Root: example.com
 Stage: clean_challenge
{
 :change_info => {
 :id => "/change/CE90OICFSN00C",
 :status => "PENDING",
 :submitted_at => 2016-08-08 17:55:15 UTC
 }
}
--------------------<
 + Challenge is valid!
 + Requesting certificate...
 + Checking certificate...
 + Done!
 + Creating fullchain.pem...
-------------------->
 Domain: test.example.com
 Root: test.example.com
 Stage: deploy_cert
 Certs: /Users/jmreicha/test/letsencrypt.sh/certs/test.example.com/cert.pem
--------------------<
 + Done!

The entire process of creation and verification should take less than a minute and when it’s done will drop out a certificate for you.

Here is a dump of the commands used to get from 0 to issuing a certficiate with the dns-01 challenge, assuming you already have AWS set up and configured.

git clone https://github.com/lukas2511/letsencrypt.sh.git
cd letsencrypt
curl -o route53.rb https://gist.githubusercontent.com/tache/3b6760784c098c9139c6/raw/33fe6e0791a7d40ce7cdf14019b7d31801d4ab05/hook.rb
chmod +x route53.rb
sudo gem install aws-sdk pry domainitrix awesome_print:1.6.0
./letsencrypt.sh --cron --domain yourdomain.example.com --hook ./route53.rb --challenge dns-01

Conclusion

There are other LE clients out there that are working on implementing DNS support including LEGO and Let’s Encrypt (now called certbot), with more clients adding the additional support and functionality all the time.  I like the letsencrypt.sh script because it is simple, easy to use, and it just works out of the box,with only a few tweaks needed.

As mentioned above, I have a feeling that automated certificates are the future as automation is becoming increasingly more common for these traditionally manual types of administration tasks.  Getting to know how to issue certificates automatically and learning how to use the tooling to create them is a great skill to have for any DevOps or operations person moving forward.

Read More

My take on the NoOps movement

I recently attended DevOps Days Portland, where Kelsey Hightower gave a nice Keynote about NoOps.  I had heard of the terms NoOps in passing before the conference but never really thought much about it or its implications. Kelsey’s talk started to get me thinking more and more about the idea and what it means to the DevOps world.

For those of you who aren’t familiar, NoOps is a newer tech buzzword that has emerged to describe the concept that an IT environment can become so automated and abstracted from the underlying infrastructure that there is no need for a dedicated team to manage software in-house.

Obviously the term NoOps has caused some friction between the development world and operations/DevOps world because of its perceived meaning along with a very controversial article entitled “I Don’t Want DevOps.  I Want NoOps.” that kicked the whole movement off and sparked the original debate back in 2011.  The main argument from people who work in operations is that there will always be servers running somewhere, as a developer you can’t just magically make servers go away, which I agree with 100%.  It is incredibly short sighted to assume that any environment can work in a way where operations in some form need not exist.

Interestingly though, if you dig into the goals and underlying meaning of NoOps, they are actually fairly reasonable to me when boiled down.  Here are just a few of them, borrowed from the article and Kelsey’s talk:

  • Improve the process of deploying apps
  • Not just VM’s, release management as well
  • Developers don’t want to deal with operations
  • Developers don’t care about hardware

All of these goals seem reasonable to me as an operations person, especially not having to work with developers.  Therefore, when I look at NoOps I don’t necessarily take the ACTUAL underlying meaning of it be to work against operations and DevOps, I look at it as developers trying to find a better way to get their jobs done, however misguided their wording and mindset.  I also see NoOps, from an operations perspective as a shift in the mindset of how to accomplish goals, to improve processes and pipelines, which is something that is very familiar to people who have worked in DevOps.

Because of this perspective, I see an evolution in the way that operations and DevOps works that takes the best ideas from NoOps and applies them in practical ways.  Ultimately, operations people want to be just as productive as developers and NoOps seems like a good set of ideas to get on the same page.

To be able to incorporate ideas from NoOps as cloud and distributed technologies continue to advance, operations folks need to embrace the idea of programming and automation in areas that have been traditionally managed manually as part of the day to day by operation folks in order to abstract away complicated infrastructure and make it easier for developers to accomplish their goals. Examples of these types of things may include automatically provisioning networks and VLAN’s or issuing and deploying certificates by clicking a button.  As more of the infrastructure gets abstracted away, it is important for operations to be able to automate these tasks.

If anything, I think NoOps makes sense as a concept for improving the lives of both developers and operations, which is one facet that DevOps aims to help solve.  So to me, the goals of NoOps are a good thing, even though there has been a lot of stigma about it.  Just to reiterate, I think it is absurd for anybody to say that jobs of operations will going away anytime soon, the job and responsibilities are just evolving to fit the direction other areas of the business are moving.  If anything, the skills of managing cloud infrastructure, automation and building robust systems will be in higher demand.

As an operations/DevOps person just remember to stay curious and always keep working on improving your skill set.

Read More

Setting up a Jenkins 2.0 pipeline

Introduction

The new Jenkins pipeline integration in 2.0 is pretty awesome and is a great way to add more automation to Jenkins.In this post we will set up Jenkins so that we can write our own custom libraries for Jenkins to use with the pipeline.

One huge benefit of the new pipeline integration in to the core components of Jenkins is the idea of a Jenkinsfile, which enables a way to automatically execute Jenkins jobs on the repo automatically, similar to the way TravisCI works.  Simply place a Jenkinsfile in the root of the repo that you wish to automate, set up your webhook so that events to GitHub automatically trigger the Jenkins job and let Jenkins take care of the build.

There are a few very good guides for getting this functionality setup.

Unfortunately, while these guides/docs are very informative and useful they are somewhat confusing to new users and glaze over a few important steps and details that took me longer than it should have to figure out and understand.  Therefore the focus will be on some of the details that the mentioned guides lack, especially setting up the built in Jenkins Git repo for accessing and working with the custom pipeline libraries.

Setup

There are many great resources out there already for getting a Jenkins server up and running.  For the purposes of this post it will be assumed that you have already create and setup a Jenkins instance, using one of the other Digital Ocean [tutorials](https://www.digitalocean.com/community/tutorials/?q=jenkins).

The first step to getting the pipeline set up, again assuming you have already installed Jenkins 2.0 from one of the guides linked above, is to enable the Jenkins custom Git repo for housing unique pipeline libraries that we will write a little bit later on.  There is a section in the workflow plugin tutorial that explains it, but is one of the confusing areas and is buried in the documentation so it will be covered in more detailed below.

In order to be able to clone, read and write to the built in Jenkins Git repo, you will need to add your SSH public key to the server.  To do this, the first step will be to configure the server per the SSH plugin and configuring a port to connect to so that the repo can be cloned.  This can be found in Jenkins -> Configuration.  In this example I used port 2222.

ssh port configuration

As always security should be a concern, so make sure you have authentication turned on.  In this example, I am using GitHub authentication but the process will be similar for other authentication methods.  Also make sure you use best practices in locking down any external access by hardening SSH or using other ways of blocking access.

After the Git server has been configured, you will need to add the public key for your user in Jenkins.  This was another one of the confusing parts initially.   The section to add your personal SSH public key was buried in docs that were glossed over, the page can be found here.  The location in Jenkins to add this key is located here,

https://jenkins.example.com/user/<username>/configure


public ssh key

If you don’t know where your public SSH key is located you can get it from the following command.

cat ~/.ssh/id_rsa.pub

Just copy that certificate and paste it into The Public SSH Keys in the Jenkins menu.

Now that you have the built in Jenkins Git repo configured you can clone it via the instructions from the above tutorial.

git clone ssh://<jenkins_username>@jenkins.example.com:2222/workflowLibs.git

Notice that we are using port 2222.  This is the port we configured via the SSH plugin from above.  The port number can be any port you like, just make sure to keep it consistent in the configuration and here.

Working with the pipeline

With the pipeline library repo cloned, we can write a simple function, and then add it back in to Jenkins.  By default the repo is called workflowLibs.  The basic structure of the repo is to place your custom functions is the vars directory.  Within the vars directory you will create a .groovy file for the function and a matching .txt file any documentation of the command you want to add.  In our example let’s create a hello function.

Create a hello.groovy and a hello.txt file.  Inside the hello.groovy file, add something similar to the following.

echo ‘Hello world!’

Go ahead and commit the hello.groovy file, don’t worry about the hello.txt file.

git add hello.groovy

git commit -m “Hello world example”

git push (You may need to set your upstream)

Obviously this function won’t do much.  Once you have pushed the new function you should be able to view it in the dropdown of pipeline functions in the Jenkins build configuration screen.

NOTE:  There is a nice little script testing plugin built in as part of the pipeline now called snippet-generator.  If you want to test out small scripts on your Jenkins server first before committing and pushing any local changes you can try out your script first in Jenkins.  To do this open up any of your Jenkins job configurations and then click the link that says “Pipeline syntax” towards the bottom of the page.

Pipeline configuration

Here’s what the snippet generator looks like.

snippet generator

From the snippet-generator you can build out quite a bit of the functionality that you might want to use as part of your pipeline.

Configuring the job

There are a few different options for setting up Jenkins pipelines.  The most common types are the Pipeline or the Multibranch Pipeline.  The Pipeline implements all of the scripting capabilities that have been covered so that the power of the Groovy scripting language can be leveraged in the Jenkins job as well as things like application life cycles (via stages) which makes CI/CD much easier.

The Multibranch Pipeline augments the functionality of the Pipeline by adding in the ability to index branches from SCM so that different branches can be easily built and tested.  The Multibranch Pipeline is especially useful for larger projects that have many developers and feature branches being worked on because each one of the branches can be tracked separately so developers don’t need to worry as much about overlapping with others work.

Taking the pipeline functionality one step further, it is possible to create a Jenkinsfile with all of the needed pipeline code inside of a repo that so that it can be built automatically.  The Jenkinsfile basically is used as a blueprint used to describe the how and what of a project for its build process and can leverage any custom groovy functions that you have written that are on the Jenkins server.

Using a the combination of a GitHub webhook and a Jenkinsfile in a Git repo it is easy to automatically tell your Jenkins server to kick off a build every time a commit or PR happens in GitHub.

Let’s take a look at what an example Jenkinsfile might look like.

node {

stage ‘Checkout’

// Checkout logic goes here

stage ‘Build’

// Build logic goes here

stage ‘Test’

// Test logic goes here

stage ‘Deploy’

// Deploy logic goes here

}

This Jenkinsfile defines various “stages”, which will run through a set of functions described in each stage every time a commit has been pushed or a PR has been opened for a given project.  One workflow, as shown above, is to segment the job into build, test, push and deploy stages.  Different projects might require different stages so it is nice to have granular control of what the job is doing on a per repo basis.

Bonus: Github Webhooks

Configuring webhooks in GitHub is pretty easy as well.  SCM is fairly standard these days for storing source code and there are a number of different Git management tools so the steps should be very similar if using a tool other than GitHub.  Setting up a webhook in GitHub can be configured to trigger a Jenkins pipeline build when either a commit is pushed to a branch, like master, or a PR is created for a branch.  The advantages of using webhooks should be pretty apparent, as builds are created automatically and can be configured to output their results to various different communication channels like email or Slack or a number of other chat tools.  The webhooks are the last step in automating the new pipeline features.

If you haven’t already, you will need to enable the GitHub plugin (https://wiki.jenkins-ci.org/display/JENKINS/GitHub+Plugin) in order to use the GitHub webhooks.  No extra configuration should be needed out of the box after installing the plugin.

To configure the webhook, first make sure there is a Jenkinsfile in the root directory of the project.  After the Jenkinsfile is in place you will need to set up the webhook.  Navigate to the project settings that you would like to create a webhook for, select ‘Settings’ -> ‘Webhooks & services’ .  From here there is a button to add a new webhook.

adding a webhook

Change the Payload URL to point at the Jenkins server, update the Content type to application/x-www-form-urlencoded, and leave the secret section blank.  All the other defaults should be fine.

After adding the webhook, create or update the associated job in Jenkins.  Make sure the new job is configured as either a pipeline or multibranch pipeline type.

pipeline job

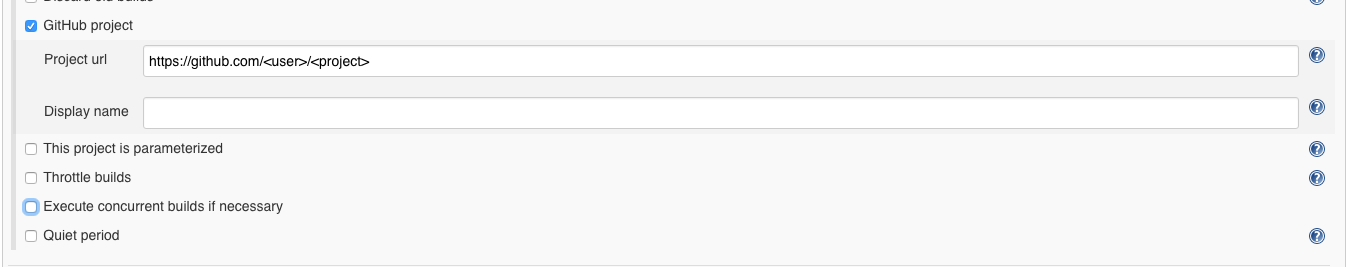
In the job configuration point Jenkins at the GitHub URL of the project.

configure the job

Also make sure to select the build trigger to ‘Build when a change is pushed to GitHub’.

more configuration

You may need to configure credentials if you are using private GitHub repos.  This step can be done in Jenkins by navigating to ‘Manage Jenkins’ -> ‘Credentials’ -> ‘Global’.  Then Choose ‘Add Credentials’ and select the SSH key used in conjunction with GitHub.  After the credentials have been set up there should be an option when configuring jobs to use the SSH key to authenticate with GitHub.

Conclusion

Writing the Jenkinsfiles and custom libraries can take a little bit of time initially to get the hang of but are very powerful.  If you already have experience writing Groovy, then writing these functions and files should be fairly straight forward.

The move towards pipelines brings about a number of nice features.  First, you can keep track of your Jenkins job definition simply by adding a Jenkinsfile to a repo, so you get all of the nice benefits of history and version tracking and one central place to keep your build configurations.  Because groovy is such a flexible language, pipelines give developers and engineers more options and creativity in terms of what their build jobs can do.

One gotcha of this process is that there isn’t a great workflow yet for working with the library functions, so there is a lot of trial and error to get custom functionality working correctly.  One good way to debug is to set up a test job and watch for errors in the console output when you trigger a build for it.  The combination of the snippet generator script tester though this process has become much easier.

Another thing that can be tricky is the Groovy sandbox.  It is mostly and annoyance and I would not suggest turning it off, just be aware that it exists and often times needs to be worked around.

There are many more features and things that you can do with the Pipeline so I encourage readers to go out and explore some of the possibilities, the docs linked to above are a good place for exploring many of these features.  As the pipeline matures, more and more plugins are adding the ability to be configured via the pipeline workflow, so if something isn’t possible right now it probably will be very soon.

Happy Jenkins pipelining!

Read More